Table 4From “What is an A/B test? randomized controlled trials, statistical power, and governance”
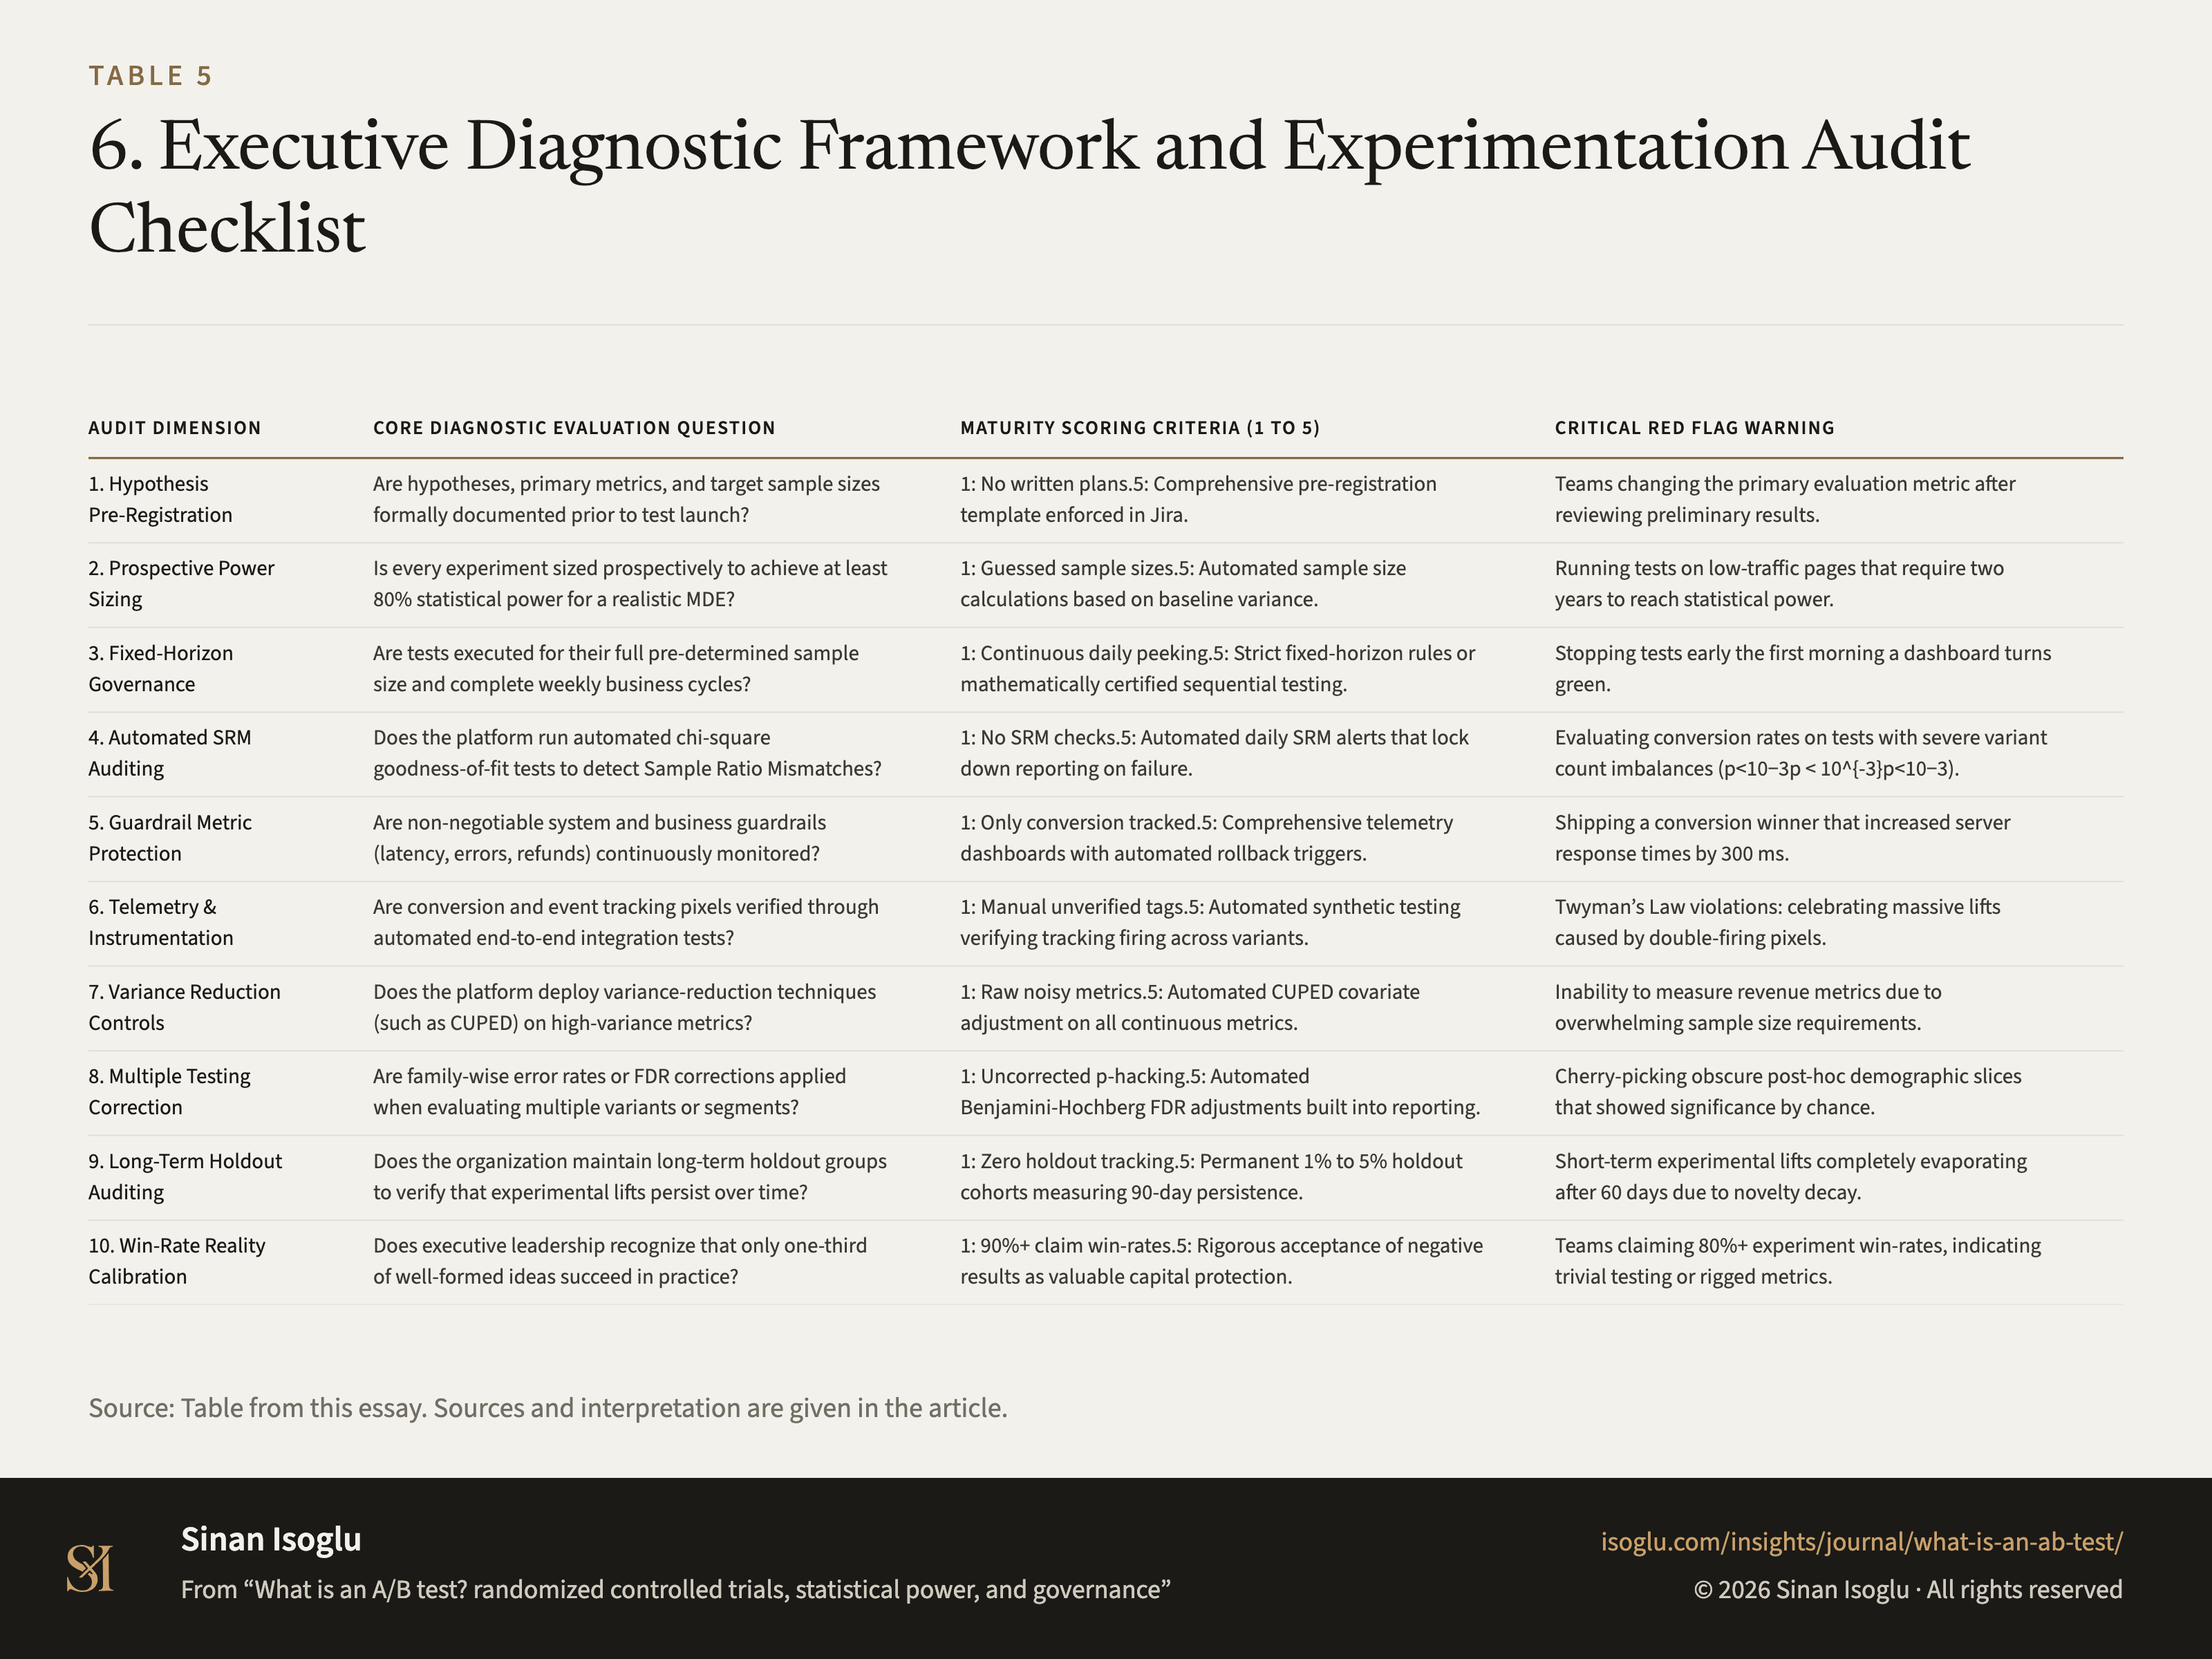
How do you audit your own experimentation programme?
Table 4How do you audit your own experimentation programme?
| Audit Dimension | Core Diagnostic Evaluation Question | Maturity Scoring Criteria (1 to 5) | Critical Red Flag Warning |
|---|---|---|---|
| 1. Hypothesis Pre-Registration | Are hypotheses, primary metrics, and target sample sizes formally documented prior to test launch? | 1: No written plans. 5: Comprehensive pre-registration template enforced in Jira. | Teams changing the primary evaluation metric after reviewing preliminary results. |
| 2. Prospective Power Sizing | Is every experiment sized prospectively to achieve at least 80% statistical power for a realistic MDE? | 1: Guessed sample sizes. 5: Automated sample size calculations based on baseline variance. | Running tests on low-traffic pages that require two years to reach statistical power. |
| 3. Fixed-Horizon Governance | Are tests executed for their full pre-determined sample size and complete weekly business cycles? | 1: Continuous daily peeking. 5: Strict fixed-horizon rules or mathematically certified sequential testing. | Stopping tests early the first morning a dashboard turns green. |
| 4. Automated SRM Auditing | Does the platform run automated chi-square goodness-of-fit tests to detect Sample Ratio Mismatches? | 1: No SRM checks. 5: Automated daily SRM alerts that lock down reporting on failure. | Evaluating conversion rates on tests with severe variant count imbalances ($p < 10^{-3}$). |
| 5. Guardrail Metric Protection | Are non-negotiable system and business guardrails (latency, errors, refunds) continuously monitored? | 1: Only conversion tracked. 5: Comprehensive telemetry dashboards with automated rollback triggers. | Shipping a conversion winner that increased server response times by 300 ms. |
| 6. Telemetry & Instrumentation | Are conversion and event tracking pixels verified through automated end-to-end integration tests? | 1: Manual unverified tags. 5: Automated synthetic testing verifying tracking firing across variants. | Twyman's Law violations: celebrating massive lifts caused by double-firing pixels. |
| 7. Variance Reduction Controls | Does the platform deploy variance-reduction techniques (such as CUPED) on high-variance metrics? | 1: Raw noisy metrics. 5: CUPED adjustment on metrics whose pre-experiment correlation has been checked, with covariates the treatment cannot move and the unadjusted result reported beside it. | Inability to measure revenue metrics due to overwhelming sample size requirements. |
| 8. Multiple Testing Correction | Are family-wise error rates or FDR corrections applied when evaluating multiple variants or segments? | 1: Uncorrected p-hacking. 5: Automated Benjamini-Hochberg FDR adjustments built into reporting. | Cherry-picking obscure post-hoc demographic slices that showed significance by chance. |
| 9. Long-Term Holdout Auditing | Does the organization maintain long-term holdout groups to verify that experimental lifts persist over time? | 1: Zero holdout tracking. 5: Permanent 1% to 5% holdout cohorts measuring 90-day persistence. | Short-term experimental lifts completely evaporating after 60 days due to novelty decay. |
| 10. Win-Rate Reality Calibration | Does executive leadership recognize that only one third of the ideas tested at Microsoft improved the metric they were designed to improve? | 1: 90%+ claim win-rates. 5: Rigorous acceptance of negative results as valuable capital protection. | Teams claiming 80%+ experiment win-rates, indicating trivial testing or rigged metrics. |
Swipe or scroll horizontally if the table is wider than your screen.
Source: Table from this essay. Sources and interpretation are given in the article.
From the essay
From the research bench
What is an A/B test? randomized controlled trials, statistical power, and governance
An A/B test is a randomized experiment comparing two concurrent variants to measure the causal impact of a single change on commercial performance.
Read the essayThis exhibit belongs to an essay: the numbers live here, the argument lives there.
Cite or embed
Related exhibits
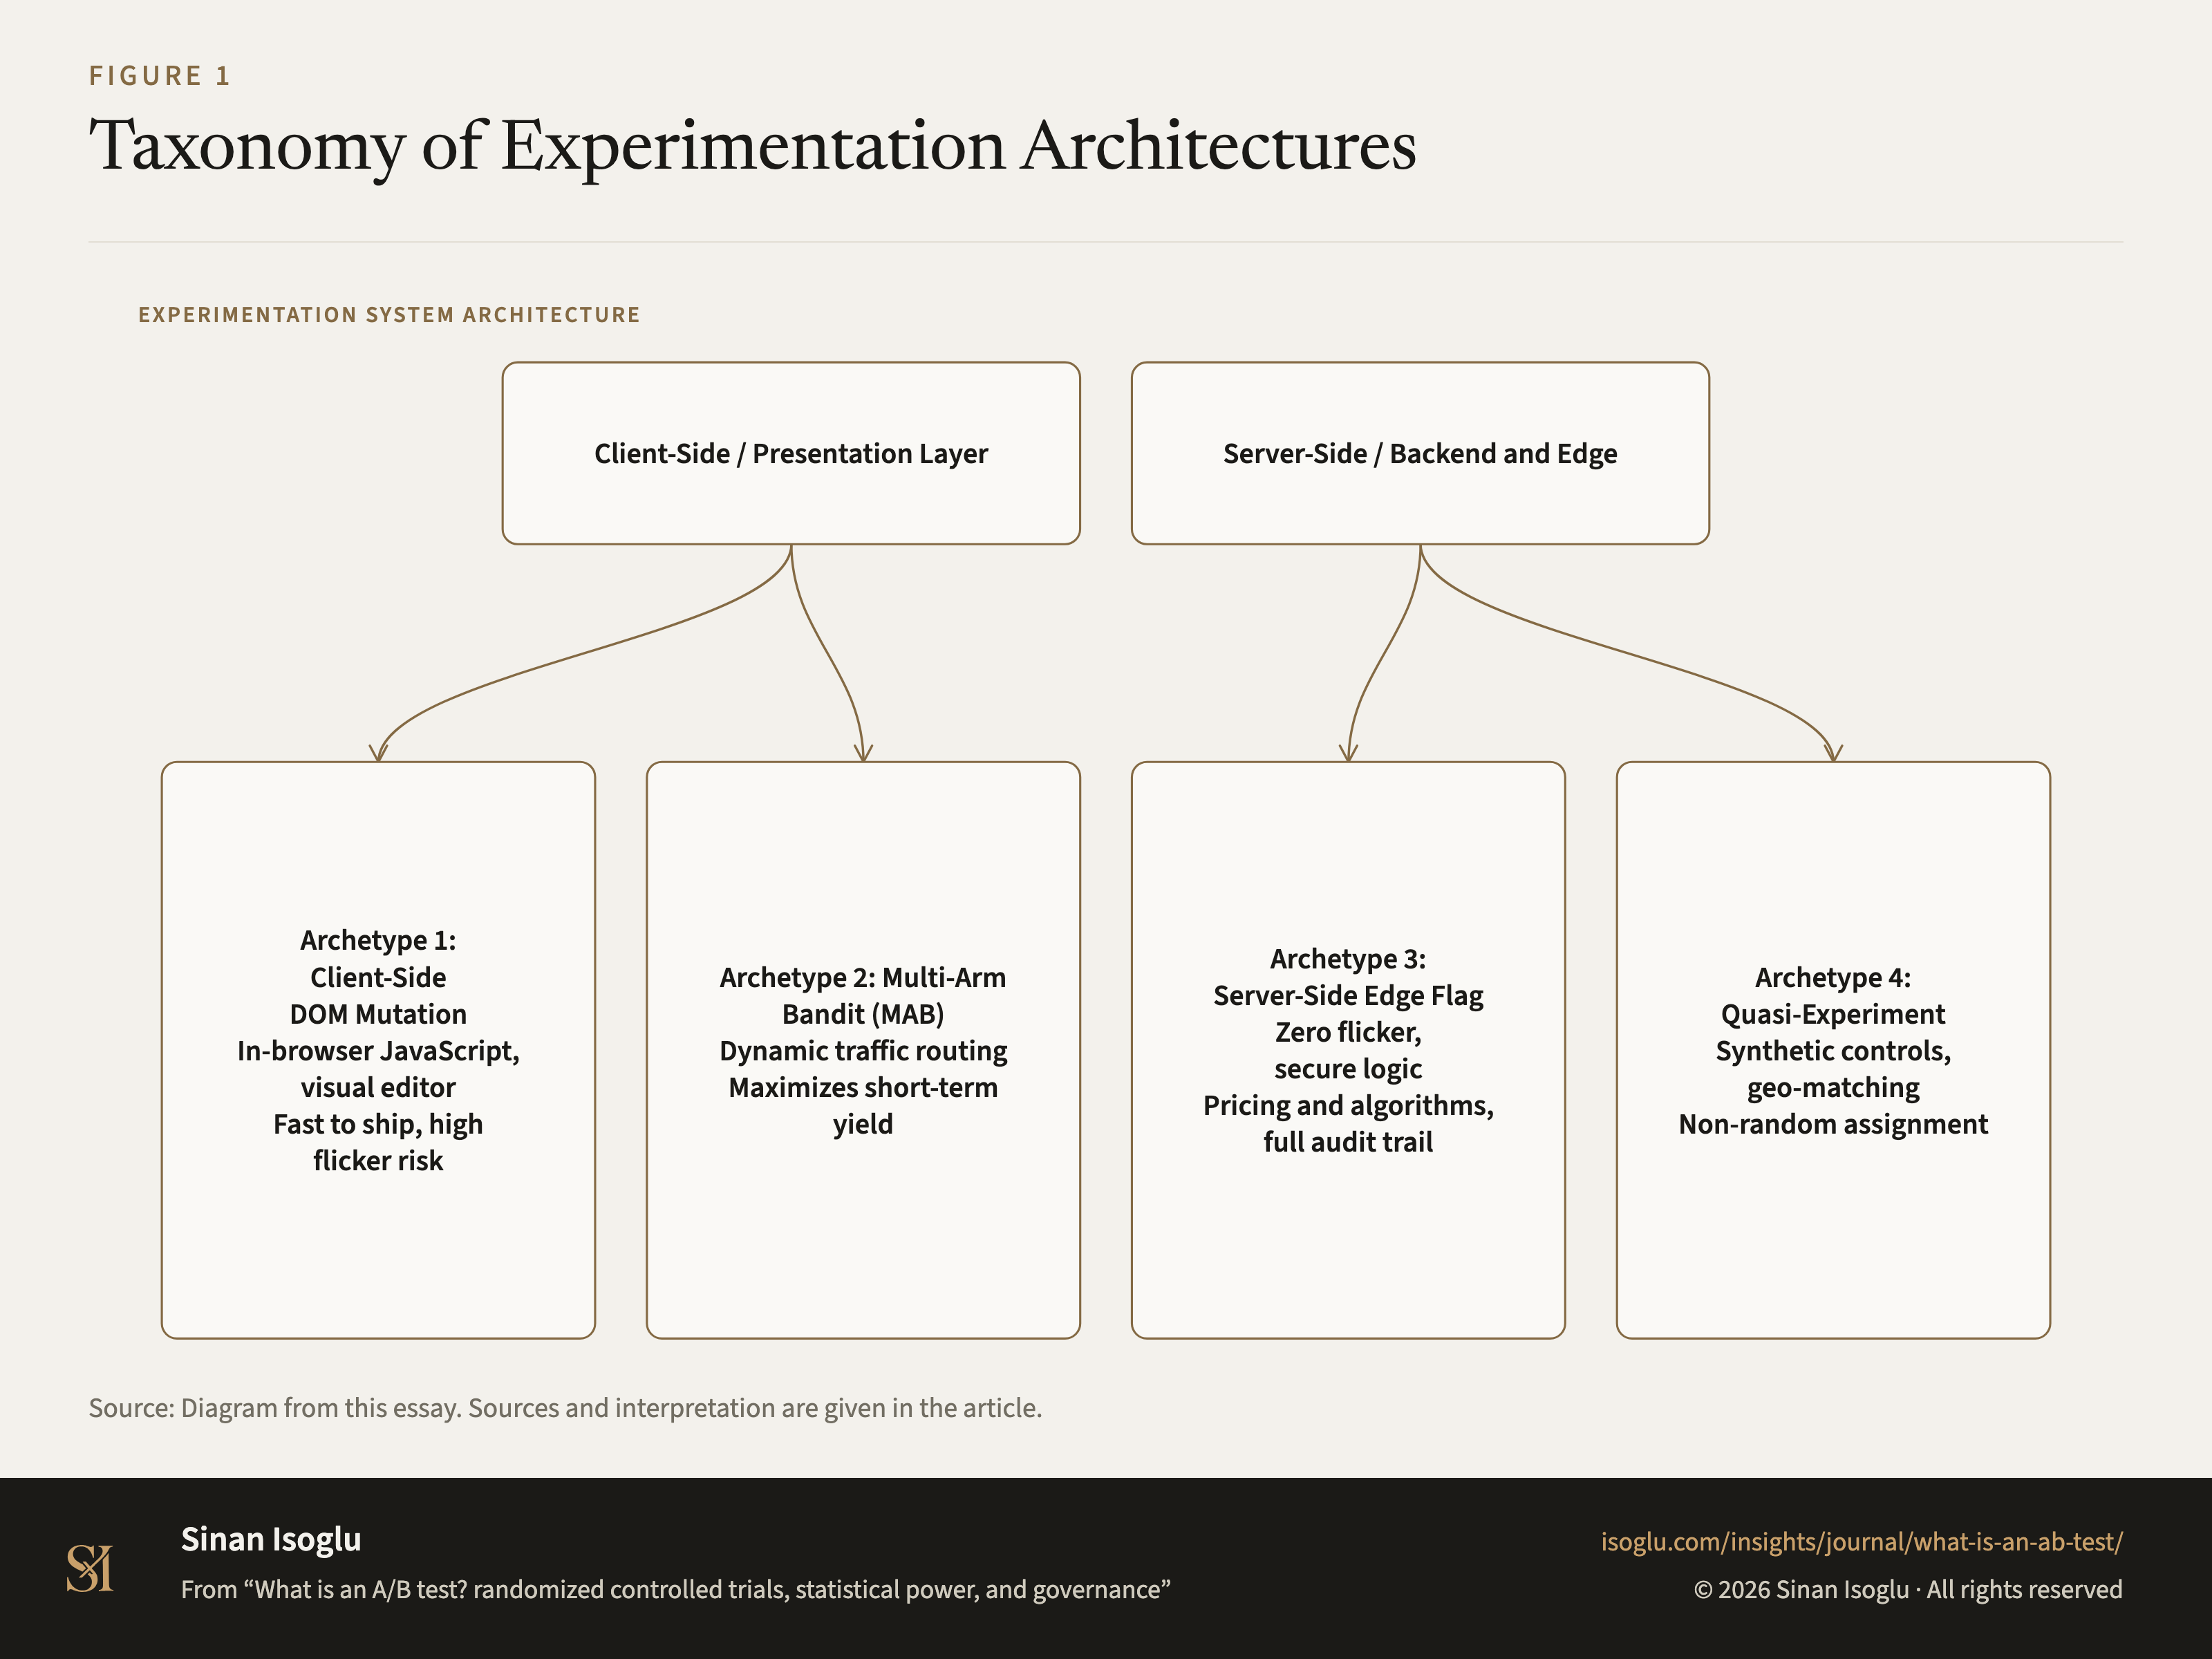
Figure 2Figure
Taxonomy of Experimentation Architectures
What is an A/B test? randomized controlled trials, statistical power, and governance
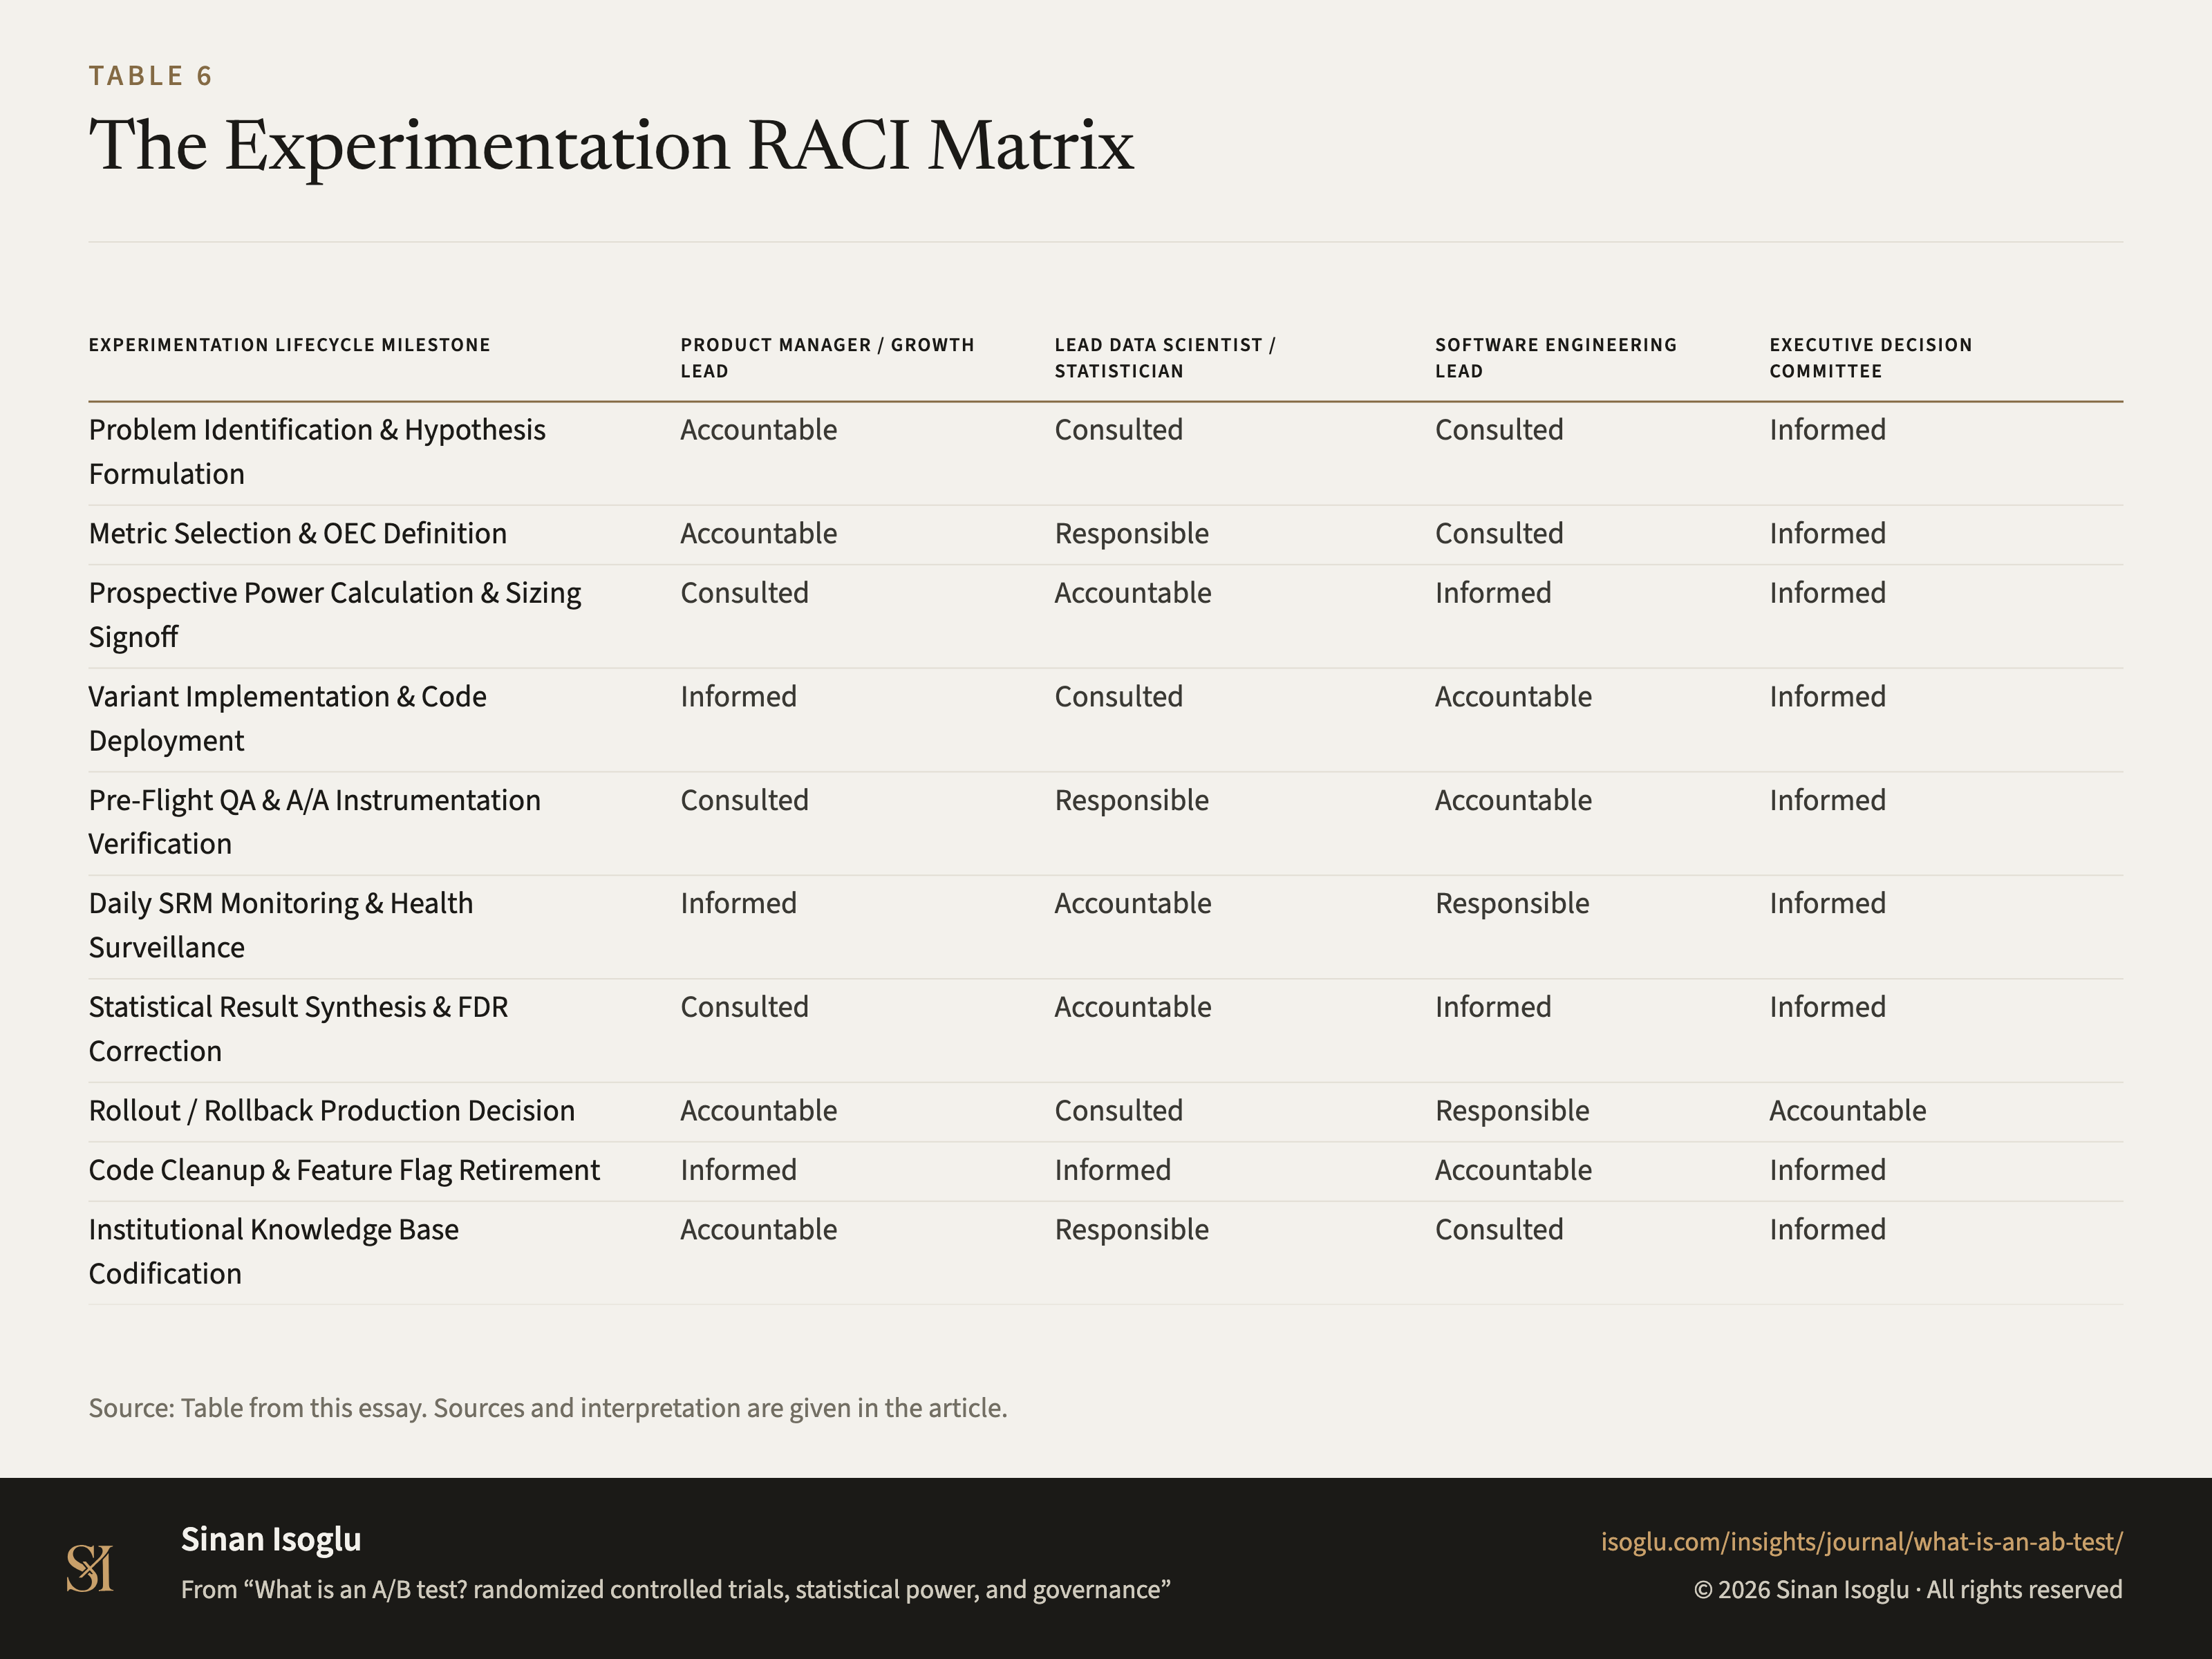
Table 5Table
The Experimentation RACI Matrix
What is an A/B test? randomized controlled trials, statistical power, and governance
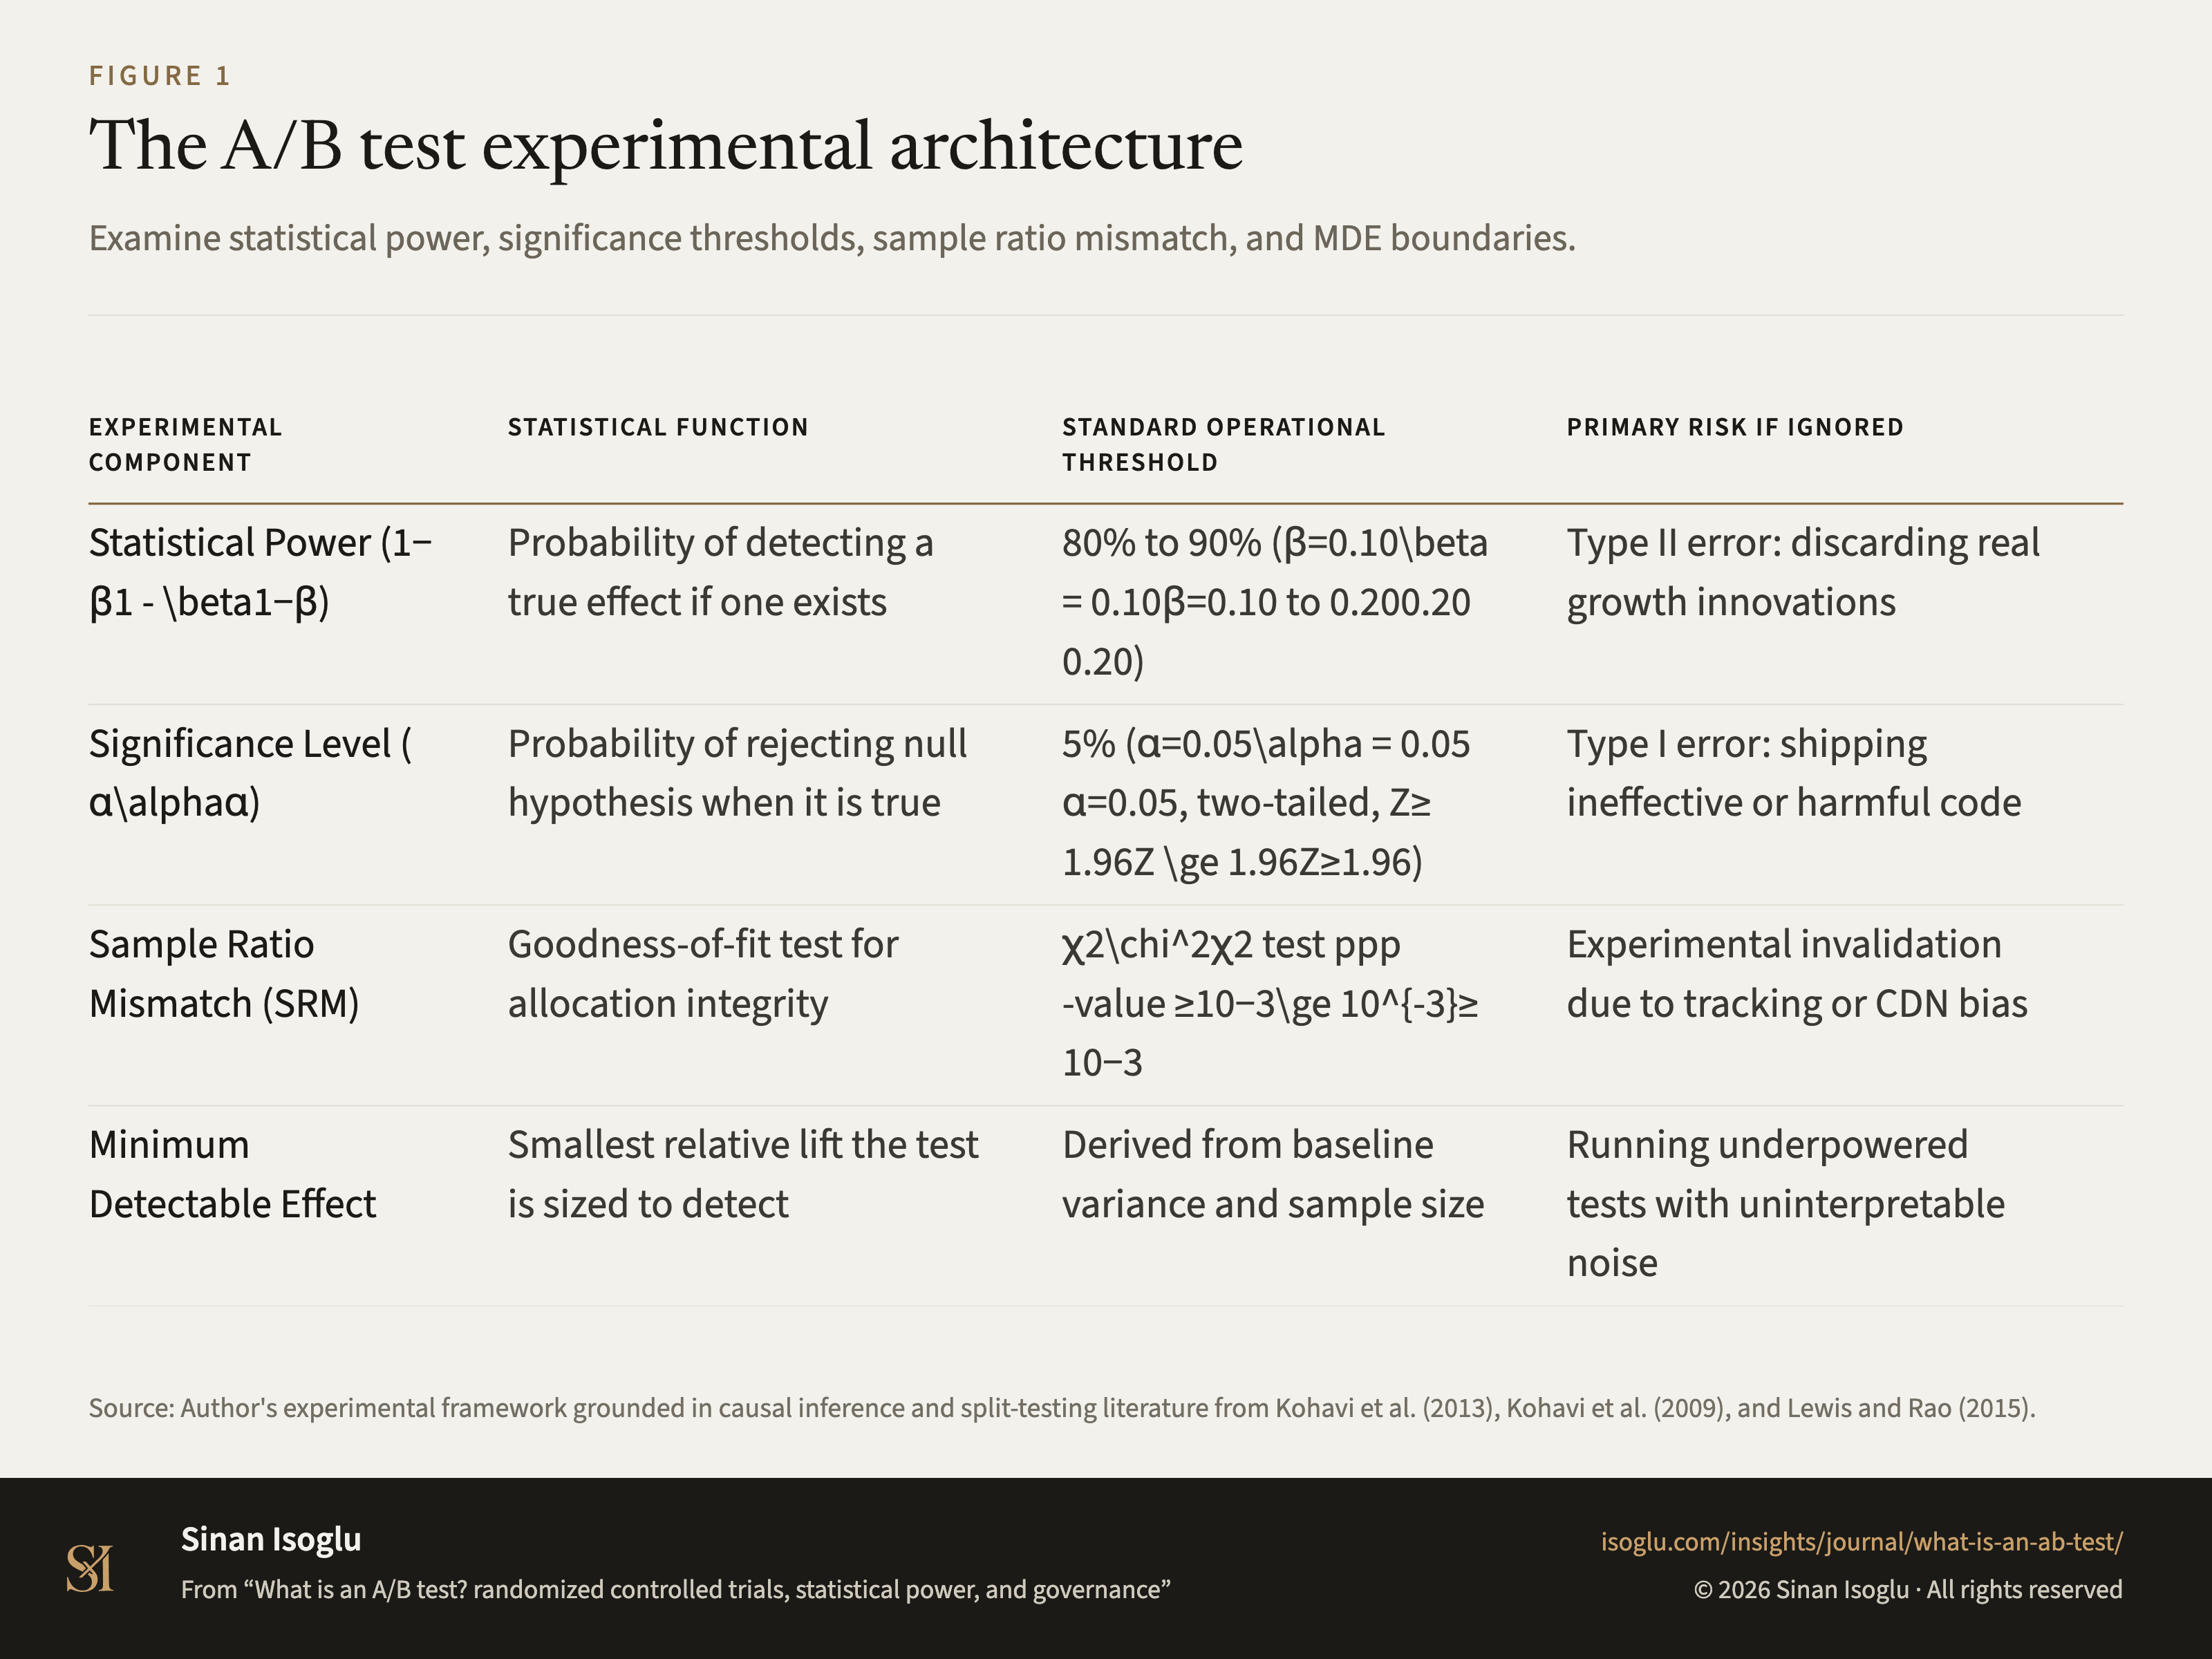
Figure 1Figure
The A/B test experimental architecture
What is an A/B test? randomized controlled trials, statistical power, and governance
Contact
Bring the question you're working on.
Research, a guest lecture, or a commercial question.